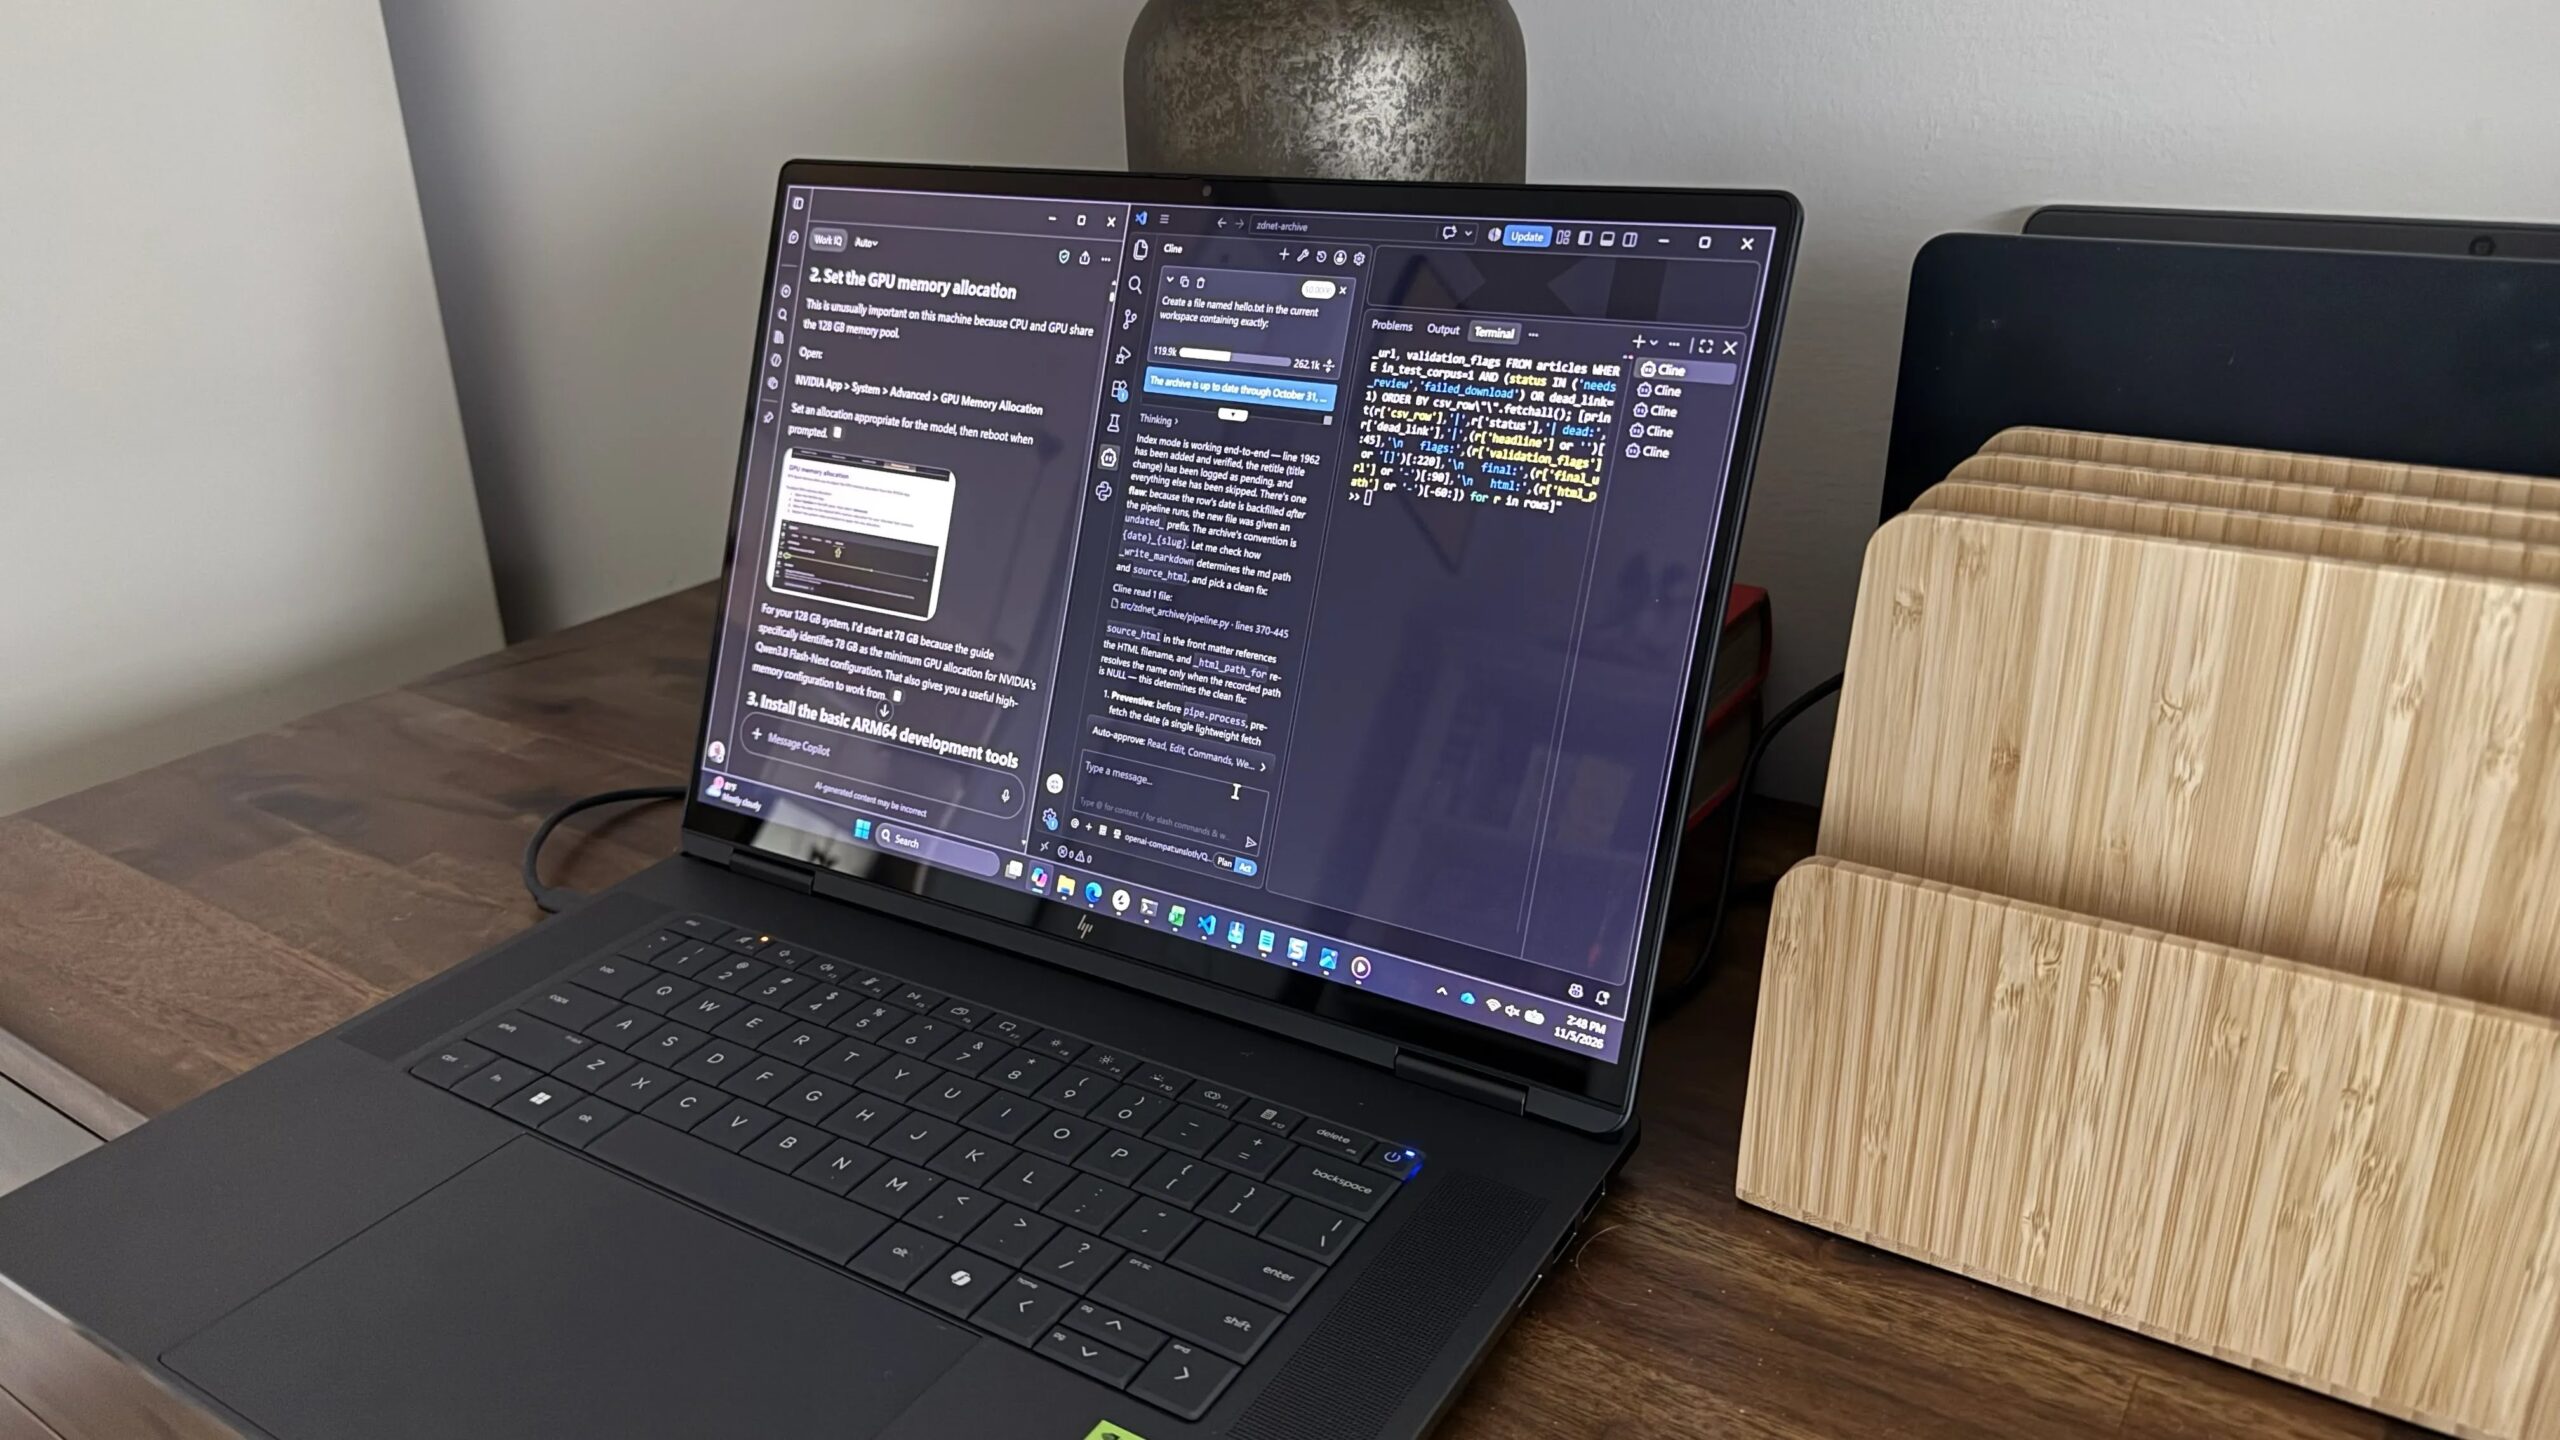
ZDNET Key Takeaways: PCs built with the Nvidia RTX Spark architecture excel at AI tasks. Running a local open weights model has no token fees or usage limits. The biggest advantage of running a local AI model is privacy. At the dawn of the PC era, legendary PC Magazine editor Bill Machrone came up with Machrone’s Law: “The machine you want will always cost around $5,000.” Maybe that number is a little higher today thanks to the current RAM crisis, but adjusted for inflation, Machrone’s Law still holds. The proof? I have a $7,000 laptop on my desk right now and I must confess that I really want it. Also: I put Lenovo’s RTX Spark laptop through a completely crazy AI coding test, and it passed. The HP OmniBook Ultra is a real beast. It’s powered by Nvidia’s RTX Spark, with 128GB of unified memory, 2TB of fast NVMe Gen5 storage, and an excellent 16-inch OLED display. It weighs almost five pounds, but it’s really less of a laptop PC and more of a personal data center, delivering 1 petaflop of FP4 AI performance. I am not the target market for this PC. But after using it for a few weeks, I’m seriously tempted. For AI-related work, its GPU has many times the power of a regular Copilot+ PC and is able to take full advantage of unified memory. How Local AI Moved Through My Project One of the reasons my project completed so quickly was that I was able to run it without interruptions. I used Copilot to help me set up the framework initially, using the open source llama.cpp inference runtime, the open weight Qwen3.8-27B large language model, and a coding harness called Cline, which runs as an extension in Visual Studio Code. With a little extra help from Copilot, I set up those tools, wrote a detailed spec for the app I wanted, sent it to Cline, and then stood back and watched. I had a good general idea of what all those components were doing, but it would have taken me weeks of trial-and-error reading, studying, and manual installation to get everything up and running. Using PowerShell scripts that Copilot wrote, I got the project up and running in half an hour. Reading the ongoing comments while the coding agent “thinks” was occasionally hilarious. Screenshot by Ed Bott/ZDNET While the project was running, I was able to see the AI “reasoning” in real time. Every once in a while he would ask me to approve something, but mostly I would write code, run tests, look at the results, modify the code, run some more tests, etc. The whole process was a textbook example of “human agent coding in the loop”, and all I had to do was check in from time to time to see how things were going. I knew it was busy because when the LLM was running, I could hear the fan spinning from across the room. Surprisingly, the machine never got too hot; Still, this is the kind of work that’s best done with the laptop on a desktop, not on a lap. Plus: I can access my home PCs remotely for free; You can do it too (no VPN needed). I gave the LLM a spreadsheet full of links to my articles, which I had painstakingly created over the past two years. Not only did it find and retrieve nearly every article on that list, it created a separate routine to retrieve pages from the Internet Archive’s Wayback Machine for about 90 links that returned 404 errors, and then presented me with a list of another 90 or so pages that it couldn’t retrieve at all. It took us maybe 30 minutes to review and resolve that last set of issues. After all was said and done, I had two folders, each containing 1,951 files: one in raw HTML and the second in Markdown format. And to conclude, I had my local AI create a simple script that I can run to add new posts to the archive as they are published. I can’t begin to tell you how happy this result made me. How much did it cost? The entire project used 479 LLM inference calls and processed almost 50 million logical tokens, with a total net cost of exactly $0.00. One of the most frustrating aspects of using these modern AI coding harnesses is that there is no way to estimate how many tokens they will use. I could have used a commercial AI subscription to do this job, but I would have been flying blind. None of the companies that sell those plans can tell you how much a given project will cost. Your actual consumption (and therefore the final bill) depends on factors that you cannot know in advance. How much code does the agent need to keep in context? How many iterations and debugging cycles will it require? What models will you use? Also: Is Claude Code really faster with message threads? I did the math on my ChatGPT Plus (with Codex), Claude Code Pro, or GitHub Copilot registrations, all of which cost between $10 and $20 per month. That’s more than enough for a simple task, but for this project, you would have quickly reached the usage limits with those entry-level plans. To continue working on a $20/month plan, you would have had to take frequent breaks, purchase additional credits, or upgrade to a $100/month plan with higher usage limits, such as ChatGPT Pro, Claude Code Max, or GitHub Copilot Max. After looking at those numbers, I had an idea of where Anthropic, OpenAI, and Microsoft’s business models are headed. Even for $100 a month, if I had decided to run some even more ambitious projects, I could have easily found myself rate-limited, with work having to wait hours or days for the next cycle to start. Microsoft’s flagship RTX Spark laptop, the Surface Laptop UltraKyle Kucharski/ZDNET For serious programmers, those bills can get very expensive. On a recent episode of Nilay Patel’s Decoder podcast, analyst Joey Brookhart offered a surprising statistic: “The top 5 percent of Claude Code users spend $18,000 a year on average. Users who don’t use Claude Code spend much less than $75 a month.” Now I know why. The biggest benefit of all Using a free open weights model with an open source coding harness gives you the freedom to experiment without worrying about the bill. But that’s only part of the story. The much bigger benefit is that you don’t send potentially sensitive or confidential data to someone else’s cloud; With a completely local AI stack, your directions, documents, and inference workloads don’t have to leave the PC at all. That wasn’t a big deal for my project, which used content that had already been published on the web. But I have a couple more apps in mind that I’d rather not share with anyone else until they’re ready. One involves a large stack of financial documents, credit card statements and invoices. I’m happy to enter that data into an LLM on my own PC, but I’m not comfortable uploading those documents to a cloud-hosted coding service. Plus: This free Windows tool is my secret weapon for setting up new PCs. Will I do enough of this type of work to justify spending $7000 on a PC? I would love to say yes, but my CPA would stare at me for a minute and then patiently explain how “return on investment” works. “No, Ed, you can’t justify this expense.” The good news is that Machrone’s Law goes hand in hand with Moore’s Law, which describes a reliable technological trend: computing power doubles every 18 months or so. That means in another three years I’ll be able to drool over a PC with four times the computing power for $7,000. But by then a configuration like this HP OmniBook Ultra will likely be a mainstream business-class machine, available for a fraction of its current price. Until then, I’ll wait. Ed Bott Senior Contributing Editor Award-winning technology journalist and Microsoft Windows expert See full bio